May 1, 2024
Updated November 14, 2026
3 minute read

Artificial Intelligence (AI) Fairness ensures that AI systems are developed and used in a fair and equitable manner. It addresses biases that may arise during data collection, model training, and deployment.
Why Study AI Fairness?
AI Fairness is crucial for several reasons. First, it promotes social justice by preventing AI systems from perpetuating or amplifying existing biases and discrimination. Second, it enhances the reliability and accuracy of AI systems by ensuring that they make decisions based on relevant factors rather than biased ones. Third, it builds trust in AI systems by ensuring that they are used in a responsible and ethical manner.
How Can Online Courses Help?
Online courses can provide a structured and accessible way to learn about AI Fairness. They offer various benefits, including:
gbjijh|
Find a path to becoming a AI Fairness. Learn more at:
OpenCourser.com/topic/gbjijh/ai
Reading list
We've selected 15 books
that we think will supplement your
learning. Use these to
develop background knowledge, enrich your coursework, and gain a
deeper understanding of the topics covered in
AI Fairness.
Co-authored by Solon Barocas, Moritz Hardt, and Arvind Narayanan, this definitive MIT Press volume formalizes statistical fairness criteria including demographic parity, equalized odds, and calibration. Rigorous mathematical proofs sit alongside sociotechnical critiques showing when purely algorithmic fixes fail.
Analyzing opaque scoring algorithms across recidivism prediction, credit underwriting, and teacher evaluation, Cathy O'Neil demonstrates how historical inequities become laundered through proxy variables. Her accessible case studies catalyzed the modern algorithmic auditing and fairness movement.
Examining commercial information retrieval and ad-ranking architectures, Safiya Umoja Noble reveals how relevance algorithms systematically demean women of color. Her work equips engineers and information scientists to recognize representational harm in search and recommendation pipelines.
Field reporting on automated welfare eligibility in Indiana, homelessness triage in Los Angeles, and child protective risk scoring in Allegheny County exposes how public-sector models penalize poverty. Practitioners learn why participatory design and impact audits are vital before deploying high-stakes classifiers.
Bridging theoretical computer science and practical model design, Michael Kearns and Aaron Roth explain how to embed fairness constraints and differential privacy directly into optimization objectives. Readers explore Pareto frontiers between accuracy and subgroup equity across real datasets.
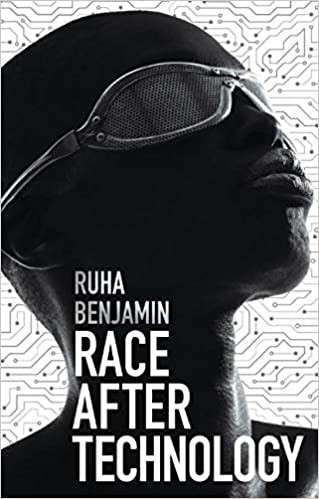
Investigating how seemingly objective technical systems reproduce racial hierarchies, Ruha Benjamin critiques superficial techno-benevolence and biased benchmark datasets. Her analysis challenges machine learning teams to interrogate who defines ground-truth labels and problem formulations.
Catherine D'Ignazio and Lauren F. Klein examine how power asymmetries shape data collection, classification, and visualization. Drawing on intersectional feminist theory, they establish concrete principles for auditing datasets and challenging structural bias in machine learning.
Olivia Gambelin translates ethical AI principles into operational governance frameworks for product teams and data leaders. Readers learn how to run algorithmic impact assessments, embed fairness checkpoints into development lifecycles, and align automated decisions with human values.
Noelle Russell presents enterprise strategies for deploying trustworthy AI systems at scale without sacrificing fairness or accountability. Case studies cover bias monitoring in production pipelines, cross-functional risk governance, and guardrails for generative models.
Centering marginalized communities directly in technology specification and evaluation, Sasha Costanza-Chock provides participatory methodologies that prevent algorithmic harm before code is written. Product teams learn how to move beyond post-hoc statistical patches toward inclusive co-design.
Tobias Baer bridges cognitive psychology and statistical modeling to help practitioners detect hidden bias in credit, hiring, and risk-scoring algorithms. Concrete mitigation patterns address proxy variables, feedback loops, and skewed training labels.
Drawing on CSIRO software engineering research, Qinghua Lu and Xiwei Xu detail architectural patterns for building auditable and fair AI systems. Design patterns span federated learning, continuous fairness testing, and transparent model documentation.
Documenting systematic gender data gaps across clinical trials, crash-test dummies, and voice recognition corpora, Caroline Criado Perez illustrates how treating male defaults as universal skews engineering outcomes. ML practitioners gain a vivid lens for spotting historical sampling bias.
Grounded in intersectional feminist scholarship, Catherine D'Ignazio and Lauren F. Klein offer seven actionable principles for auditing power asymmetries in data collection, labeling, and visualization. Case studies demonstrate how missing data and binary classifications distort machine learning outcomes.
Examining the International Classification of Diseases, apartheid racial registries, and nursing taxonomies, Geoffrey Bowker and Susan Leigh Star reveal how invisible standards valorize certain viewpoints while silencing others. Every dataset curator and ontology designer benefits from this foundational study.
For more information about how these books relate to this course, visit:
OpenCourser.com/topic/gbjijh/ai

 Save